Thursday, November 15, 2012

Mozilla XForms has gone

XTF and XML events are removed from Firefox (see this and this) and that's supposed to be a last day of Mozilla XForms project which was built on these technologies. Mozilla XForms was nearly dead for a while and it was kept alive by Philipp Wagner. Now it's over. So we decided to remove XForms accessibility support from Firefox.

XForms was a project that my Mozilla story has started from. I worked for a local company in the city I live. They created Mozilla based applications and in particular they were interested in Mozilla XForms. XForms was a really promising technology since it supported natively a model view pattern and provided a nice mechanism to map data to UI. However Mozilla based applications were written in XUL but Mozilla XForms didn't have XUL UI those days. So they decided to put me working on Mozilla XForms project to fix that. That's how I've met XForms guys: Allan Beaufour, Aaron Reed and Olli Pettay.

Year later I was moved to another project. I had a chat to Allan and I said that I'm really upset that I can't spend much time on the project anymore. After several days Allan asked: Do you still want to continue your work? I said: Of course. He said: there's an idea to make XForms accessible, I will introduce you to one guy. That's how I've met Aaron Leventhal and that's how my Mozilla accessibility story has started.

Note (just in case): XTF and XML Events were removed in Firefox 19. Firefox 17 and Firefox 18 aren't affected. That means next ESR release is not affected too.

Wednesday, November 14, 2012

Accessible Firefox: Text equivalent computation

Each accessible object may have name and description, a primary characteristic used for perceivability of the control element by the user (also referred as text equivalent). As far as I know only ARIA spec provides an algorithm of text equivalent computation. It might look strange that ARIA specifies an universal algorithm equally applicable to any markup (would it be HTML or anything else) but that's how it is. Other specs either don't address that or like  HTML spec are referred to the ARIA one. Each browser follows that algorithm this or that way.

Algorithm implemented in Firefox isn't 1 to 1 with ARIA's one but it is quite close to the version from ARIA first draft. Basically that version was written from Firefox implementation. ARIA was evaluated, Firefox was evaluated too but not always in sync with ARIA.

I realized that Firefox algorithm isn't documented anywhere so I decided to put it here to not make people read the code if they are curious about Firefox behavior. Note, Firefox might do a slightly different computations on case by case basis. In general these should considered as bugs. However this algorithm is not free from bugs as well. Let me know if you see anything suspicious.

Terms


Here is a list of used terms in algorithm description:
initial node
the DOM node the text equivalent is computed for;
current node
the DOM node currently traversed in order to compute the text equivalent for initial node;
text equivalent string
the text equivalent we have computed up until we have arrived at the current node;
string attribute
attribute whose value provides a text equivalent, for example, aria-label in case of name computation;
relation attribute
IDRefs attribute referred to other element(s) used in text equivalent computation, for example, aria-labelledby in case of name computation;
empty on purpose text equivalent
text equivalent left empty on purpose by the author, AT shouldn't try to repair it.

Algorithm


To compute the text equivalent for current node:
  1. Prepend a space if necessary: if the current node is not inline element (refer to CSS display style), append a space character if the text equivalent string is not empty.
  2. Compute the text equivalent for the current node and append it to text equivalent string:
    1. If the node is hidden and it's not a part of computation initiated by relation attribute (in other words, it's not referred by or it's not a child of hidden element referred by relation attribute) then, skip the node. ⤴
    2. If the node is a text node, then append the rendered text content if the node is not hidden, otherwise its append text content. Proceed to the next node. ⤴
    3. Append text equivalent from ARIA markup if any, otherwise append it from native markup:
      1. If text equivalent is provided by string attribute then append its value. If string attribute value is empty and the text equivalent won't be provided later by the algorithm then text equivalent is considered empty on purpose.
      2. If text equivalent is provided by relation attribute, and this node is not already part of text equivalent calculation, then within the relation attribute value, process the IDs in the order they occur and ignore IDs in that are not specified on an element in the document. For each ID's associated element, implement this text equivalent computation starting with step 1, appending the results to the text equivalent string as they are collected.⟲
    4. If the node is not initial node or if it's recursively reentered initial node but it's not the fist or last part of a text equivalent computation then append the current user-managed value of this node.
    5. If the text equivalent for this node is empty, and either the node's role allows "text equivalent from subtree" or the node is not a control and not the initial node, then recursively implement this algorithm for each child, starting with step 1.⟲
    6. If the text equivalent for this node is still empty, get it from tooltip for the current node if any.
  3. Append space if the space was added at step 1.
  4. Normalize whitespace, trimming leading and trailing space and condense other whitespace characters into a single space.

Remarks and examples


Item c.


Text equivalent computation from ARIA and native markup is nicely covered by HTML to a11y spec.

Nevertheless as example of a native markup text equivalent can be alt attribute for HTML <img> or a label from <label for> for control element. However, markup for tooltips is not used as native markup text equivalent, they are used as a last resort under item f.

In general name and description don't dupe each other so that if some markup was used as name then it won't be reused as description. For example,

  <img title="Me and Eiffel Tower">

Name is "Me and Eiffel Tower", description is empty.

But:

  <img alt="I'm in France" title="Me and Eiffel Tower">

Name is "I'm in France", description is "Me and Eiffel Tower".

Item c.i. 


Example of empty on purpose name is <img alt="">.

Item c.ii. 


Example of relation attribute processing:

  <button aria-labelledby="span" id="btn" />
  <button aria-labelledby="btn" id="btn2" /> 
  <span id="span">text</span>  

@id="btn" name is "text", aria-labelledby is processed since we don't have reentrances.
@id="btn2" doesn't have a name, aria-labelledby on @id="btn" is ignored because otherwise it would mean reentrance (@id="btn2" aria-labelledby brought us here).

Note, if the recursion only produces white space then we proceed to the next item of the algorithm. For example

  <span id="span"></span>
  <button aria-labelledby="span">press me</button>


Name of button element is "press me". The rule is also applicable to item e.

Item d.


1. By user-managed value we assume the value of accessible object. In HTML <input> case it's built from value attribute. In case of ARIA that will be aria-valuetext for example.

2. If the current node is initial node then value is not included.

  <div role="slider" aria-valuetext="right in the middle"></div>
 
Name is empty for ARIA slider.

3. But if the current node is not initial node then value is included.

  <label for="input">
    Position
    <div role="slider" aria-valuetext="right in the middle">
    </div>
  </label>
  <input id="input" type="checkbox">

Name of the checkbox is "Position right in the middle".

4. If the current node is the initial node and it was reentered then:

a. If the node is in middle of text equivalent computation then its value is included.

   <label>
     Subscribe to
     <select>
       <option>ATOM</option>
       <option>RSS</option>
     </select>
     feed.
   </label>


Name for select is "Subscribe to ATOM feed".

b. If node is not in the middle of text equivalent computation then value is omitted.

  <label>Home page: <input type="text"></label>

Name for input is "Home page:".

Monday, October 29, 2012

ARIA payback

I'm not a real part of ARIA spec development but I work with assistive technology vendors and ARIA widgets authors on ARIA support in Firefox, I'm the one who implements ARIA in Firefox. I'm focused on practical aspects of ARIA usage and often I deal with problems not addressed by ARIA spec.

Here how it usually works. We and AT developers discuss a problem and then after agreement we implement just a reasonable solution that works for AT, users and us. We don't always go for a feedback from ARIA group and actually I think there's a number of reasons why. Personally I don't go probably because
  • I think somebody else could do that since it was a group decision after all.
  • I don't always get feedback from ARIA group.
  • ARIA group is perceived as a closed group (I always run into restricted areas the other participants are referred to).
  • ARIA group structure feels complicated (there are two ARIA specs managed differently and when you have a single ARIA issue then sometimes you should go though different authorities to get a feedback).
I think it's because I didn't have a really good story of collaboration with ARIA group.

On the another hand I don't follow the ARIA spec progress. I didn't see changelogs between spec versions. I wasn't really asked for feedback as ARIA implementator in Firefox. Because all of this many changes in the spec were introduced silently for me. I don't want to blame anyone (including myself) I just want to say that ARIA spec development was in parallel universe for me.

Yes, it couldn't be forever, one day Firefox implementation should meet the spec on the crossing and we should get a bump. This day have came. ARIA spec came into candidate recommendation and we were said Firefox don't pass tests. While I was running through failing tests one by one then I realized I have concerns for half of them. It wasn't a really big surprise but I disagreed what ARIA spec states in a number of cases. Here are few examples when I had concerns.

1) ARIA abstract roles must be not exposed via standard role mechanism (see the ARIA spec):
User agents MUST NOT map roles defined in the WAI-ARIA specification as "abstract" via the standard role mechanism of the accessibility API.
It seems very reasonable since there's *no* any single reason why the AT would need it. But the statement might be colored differently if you read it as implementator. If the browser exposes only known and "good" ARIA roles then the browser is in good shape and it goes with the spec. The browser can do different approach and expose all ARIA roles (not depending whether they are known or unknown) and let the AT to decide what to do with them. You can argue whether this is a good idea or not but it can be used in the wild, for example, by scripted JAWS and certain web apps (in this case the browser is just a mediator between web app and screen reader). Also the spec doesn't deny that.

However if the browser follows this approach then we run into a problem because the browser must known about abstract roles to ignore them. Abstract roles are pure theoretical matter used to organize stuff in the spec, it's *not supposed* to be used on the web and it *won't* be used on the web but the browser *must* know about them if the browser relies on "expose any role" approach. In reality it slows down the browser for nobody's win. Ok, it's a browser problem. ARIA problem I think is the ARIA spec tries to standardize things that *aren't* supposed to be used on the web what is meaningless in general.

2) aria-checked="mixed" on radios should be mapped to "false" value (see the ARIA spec):
The mixed value is not supported on radio or menuitemradio or any element that inherits from these in the taxonomy, and user agents MUST treat a mixed value as equivalent to false for those roles.
I agree mixed value on radios don't make any sense since radios don't support tristate. But the "false" value is not a fallback value on radios. That means the browser *must* introduce a special check for the case that doesn't have *practical* usage on the web.

The problem is the candidate recommendation means nobody wants to change the spec at this point especially if it's implemented by some browsers already. It doesn't really make sense to address any issue listed above in the next spec since they don't make a difference on the web. It wouldn't be so bad to just follow the spec if we didn't have other discrepancies especially those that *make* a difference for the user.

The reality is either Firefox picks up that burden wordlessly or it gets an yoke of the browser incompatibility with the spec. No good options, huh?

Wednesday, October 17, 2012

Raiffeizen strikes back

It's a second time when Raiffeizen leaves me without money for a week. I have a bank card in Raiffeizen, an European bank. When card expires then they issue a new one but before they deliver it to me they block my existing card. They said they take care of safety of my funds and I guess I can't disagree with them: when I can't spend my money then money are safe.

They said they keep new card blocked until it's delivered to me. Also they said the new and current card have identical numbers and therefore they don't differentiate them. That's why my existing card is blocked too.

Of course they are so friendly so that they agree to unblock my card for one transaction if I stay on phone line. Say if I need to buy something and I wait in line in the supermarket then I need to call them, maybe wait for 15 minutes before they answer to me and ask them to unblock my card and greetings I can do a payment. It's also funny that I need to identify myself answering all secret questions and I need to do that when I'm surrounded by people.

They really drives me mad.

Вот уже второй раз когда Райффайзен подкладывает мне свинью, блокируя мою карту. Когда срок действия карты истекает, они выпускают новую, но пока новая карта не передана мне в руки, они блокируют мою действующую карту. Они говорят, что беспокоятся о сохранности моих средств, и я не могу не согласиться с ними: если я не могу потратить денег, то они защищены надежно. От меня, конечно.

Сказали, что новая карта заблокирована пока я ее не получил. Но потому как новая и старая карты имеют одинаковые номера и они их в действительности не различают, то моя действующая карта тоже заблокирована.

Конечно, они идут навстречу и позволяют мне разблокировать мою карту на одну транзакцию, пока я остаюсь на телефонной линии. Скажем, мне понадобилось что-нибудь купить и я стою в очереди на кассу в супермаркете. Мне нужно позвонить им, возможно подождать минут 15 пока они ответят и попросить их разблокировать карту. И - вуаля - я могу совершить покупку. Забавно еще то, что мне необходимо, конечно, идентифицировать себя, отвечая всякие секретные вопросы, пока я стою в очереди, окруженный людьми.

Они действительно издеваются.

Thursday, October 11, 2012

Firefox 16 - 18: what's new for AT developers

This summer wasn't super plenteous for features interesting for assistive technology developers. Firefox 17 was nearly barren in this sense. Thus here's a list of changes introduced in Firefox 16, Firefox 17 and Firefox 18.

ARIA

(Firefox 16) ARIA documents are now subject of document loaded event. If the author does something like:

  <div id="dialog" role="dialog" style="display: none;">A message</div>
  document.getElementById("dialog").style.display = "block";

then LOAD_COMPLETE event is fired after the dialog appears (refer to document handling in Firefox for details).

(Firefox 17) We sorted out stuff related with vertical and horizontal states.  Previously we could expose these states on the same accessible the same time regardless the value of aria-orientation attribute or expose them on elements that orientation is not applied to. Also ARIA role="scrollbar" got vertical state as default value.

(Firefox 18) If ARIA grid contains role="rowgroup" then IAccessibleTable interface went crazy, i.e. row/col/cell indexes coherence was broken.

(Firefox 18) aria-activedescendant behavior was corrected a bit. We have supported the case the spec says about: "Authors MAY use the aria-activedescendant attribute on the focused descendant of a composite widget; for example, on a textbox descendant of a combo box." This is an example these words are applicable to.

  <div id="combobox" role="combobox">
    <input id="combobox_entry" />
    <ul>
      <li id="combobox_option1" role="option">option1</li>
      <li id="combobox_option2" role="option">option2</li>
    </ul>
  </div>

If the input has DOM focus and the author changes the aria-activedescendant attribute on combobox element to point a combobox option then that combobox option gets the focus.

(Firefox 18) If ARIA role="presentation" is used on the element having ARIA global attributes or referred by ARIA relation then role="presentation" is ignored as it wasn't there. The behavior is similar if the element is focusable.

HTML

(Firefox 16) HTML5 article element is a subject of 'article' xml-roles object attribute.

Also we fixed few edge cases. Btw, they all were caught in the wild.

(Firefox 18) We didn't create a listitem accessible for HTML li element in some cases like:

  <ul id="list7">
    <li id="l7_li1" style="display:inline-block;">Oranges</li>
    <li id="l7_li2" style="display:inline; float: right;">Apples</li>
  </ul>


(Firefox 18) Table related styles used outside the table context prevented to create a correct accessible. For example,

  <h1 style="display: table-cell;">a header</h1>

didn't have a heading accessible.

States

(Firefox 18) Finally we sorted out invisible/offscreen states and the implementation corresponds to what I wrote before.

(Firefox 18) Some offscreen accessible didn't expose the offscreen state. You could see this bug at ai squared site.

Text attributes

(Firefox 16) auto-generated text attribute is supported now (refer to IAccessible2 spec). It's get exposed for auto generated CSS content (:after and :before pseudo elements) and HTML list bullets. Note, we don't expose the auto-generated object attribute anymore.

XPCOM

(Firefox 16) defaultKeyBinding attribute and getKeyBindings method of nsIAccessible interface was replaced on single accessKey attribute. Gecko always exposed either an access key (alt + letter) and/or keyboard shortcut (ctrl + letter). An ability to return many keybindings was never used.

Monday, October 8, 2012

Debugging the Firefox accessibility

Firefox 18 got a logging system that allows you to analyze accessibility related problems and bugs. It's used to debug the real life examples like web pages where thousands of things happen every second and you don't have any clue what's going wrong there. If you ever debugged a focus issue on the web then I think you agree the logging is something very helpful on this way. On the other hand logging is a great thing to understand the problem you can't reproduce (reliably).

I didn't tried the system in case when the bug reporter is unique person who can see a problem but it works quite well for analysis of automated tests intermittent failures. The difference is the test suite has own logging capabilities and it writes down every step so that you can find out where the test was stumbled. Having these logs enabled both you can see what action was performed and what happened after.

Here's couple examples how to use logging to understand the intermittent failure.


Test suite logging


Almost every accessibility related test is based on events watching, i.e. we wait for certain event before starting the next test. It's all caused by async nature of accessibility implementation in Gecko.

You can start logging by setting gA11yEventDumpToConsole variable to true. A log looks like:

registered: event type: document load complete,
  target: tabDocumentAt, arg: 0
registered: event type: document load complete,
  target: tabDocumentAt, arg: 1

Event queue:
  invoke: relations of tabs

Event type: document load complete.
  Target: ['document node', address: 0x1e3b4850, role: document,
           name: 'The Book of Mozilla, 11:9', address: 0x112ddd90].
Event type: document load complete.
  Target: ['document node', address: 0x1e3b4448, role: document,
           name: 'About:', address: 0xe253250].

*****
EQ matched: document load complete
*****

7233 ERROR TEST-UNEXPECTED-FAIL |
  accessible/relations/test_tabbrowser.xul |
  Test timed out.

It is a real world example. We wait for two document load events and as you see we receive them but only one is recognized as expected one. The problem here is we wait events in specific order but sometimes we receive them in reverse order. It happens because documents are loaded asynchronously and thus events order varies. The test was fixed.

This was a case when the test suite log gives you enough information to fix a problem. But often you know there's no expected event and that's all you have. Extra info is wanted. In this case the system logging can be helpful.


System logging


The system logging is used to log implementation internals, i.e. it serves to understand what happens under the hood. There's a bunch of modules you can track, for example, 'focus' module logs everything related with accessible focus event processing. Depending on your needs you can enable one or several modules to log. You can do that by setting up the environment variable A11YLOG, for example:

export A11YLOG=focus,tree,DOMEvents;

Alternatively you can manage the logging from java script via nsIAccessibleRetrieval interface:

var accRetrieval =
  Components.classes["@mozilla.org/accessibleRetrieval;1"].
  getService(nsIAccessibleRetrieval);
accRetrieval.setLogging("focus,tree");

Note, you need to have enhanced privileges for that. If you debug a11y automated tests then you can use enableLogging()/disableLogging() helper functions from common.js.

The system logging can be enabled on any debug or nightly build.


An example


Bug 782991 is a good example how to debug intermittent failures. The problem was the following: when link is open in a new window then document load event was missed occasionally. That's all you know. And that means you don't even know whether the window was open or not.

Since it's document loading issue then it's reasonable to enable 'docload' module. A log when test fails:

A11Y DOCLOAD: document loaded; 47:41.689
  {
    DOM id: 17D86000, acc id: 1A9545C0
    uri: chrome://browser/content/browser.xul
  }

A11Y DOCLOAD: document loaded; 47:42.014
  {
    DOM id: 0E337000, acc id: 16C60B80
    uri: http://www.example.com/
  }

A11Y DOCLOAD: document loaded *completely*; 47:42.036
  {
    DOM id: 0E337000, acc id: 16C60B80
    uri: http://www.example.com/
    document acc state: completely loaded
    document is load event target: false
  }

A11Y DOCLOAD: document loaded *completely*; 47:42.048
  {
    DOM id: 17D86000, acc id: 1A9545C0
    uri: chrome://browser/content/browser.xul
    document acc state: completely loaded
    document is load event target: false
  }

As you can see 'example.com' document gets loaded (what means the window was open) but document load event wasn't fired. In practice a log when the test doesn't fail is also helpful to find a problem:

A11Y DOCLOAD: document loaded; 02:50.695
  {
    DOM id: 0x91e97a0, acc id: 0xebaf308
    uri: chrome://browser/content/browser.xul
  }

A11Y DOCLOAD: document loaded *completely*; 02:51.043
  {
    DOM id: 0x91e97a0, acc id: 0xebaf308
    uri: chrome://browser/content/browser.xul
    document acc state: completely loaded
    document is load event target: false
  }

A11Y DOCLOAD: document loaded; 02:51.235
  {
    DOM id: 0xd9732b0, acc id: 0xd11ed40
    uri: http://www.example.com/
  }

A11Y DOCLOAD: document loaded *completely*; 02:51.302
  {
    DOM id: 0xd9732b0, acc id: 0xd11ed40
    uri: http://www.example.com/
    document acc state: completely loaded
    document is load event target: true
  }

A11Y DOCEVENT: handled 'load complete' event; 02:51.302
  {
    DOM id: 0xd9732b0, acc id: 0xd11ed40
    uri: http://www.example.com/
  }

The difference between logs is in order of the document load processing. If the 'example.com' document is processed before a document of the main Firefox window then 'example.com' document isn't considered as a target of document loading events and the test fails. It's enough to understand where the bug is and fix it.

If you look for more examples then check out bugs: bug 745788, bug 708927 and bug 691580.

Wednesday, July 18, 2012

Crimea trip

This summer we decided to make a trip along Crimean coast starting from Feodosiya and finishing at Yevpatoriya. Crimea is a beautiful place having long and rich history.

Most of pictures are made by mobile phone so they aren't really good but I hope they don't ruin the impression.

To Crimea


I booked the flight to Simferopol with layover in Saint-Petersburg by Rossiya Airlines. When we arrived to Sain-Petersbug early morning then we were surprised that our connection flight was moved to the evening. We were forced to pick up all our luggage and then we moved to Rossiya Airlines office. They said they don't have any idea why they didn't contacted us about this change. Also they said they are sorry but they cannot help us: no left luggage service, no food etc.

We moved to the center of Saint-Petersburg and took a trip on Saint-Petersburg canals. It was rainy, we were tired but Saint-Petersburg was great.

Feodosiya


Nothing really exciting about Feodosiya. A long coquina beaches around Feodosiya, a lot of sea. There are some old buildings, nice seafront and Aivazovskiy museum. A nice place as family resort.

Noviy Svet


Then we moved to Noviy Svet. This is a place I can love. Juniper forest, mountains and the sea. We lived near of the juniper forest and walked there everyday.

Juniper forest

Hurzuf


After that we moved to Hurzuf. Hurzuf is a nice place as well: narrow and winding streets going up and down, Checkov's dacha.


We stayed in the hotel located in Artek - well known USSR pioneer camp. Artek has huge territory over 200 hectares (over 500 acres) and no doubts it's one of beautiful places I've ever seen.


Before Artek the Russian resort named SuukSu was located here.


There are Aldary here - two rocks in the sea. There's a Pushkin crag, they said he liked to visit these places.


Chaliapin wanted to build there Palace of Arts but failed to do that because of revolution.


The label says: "In Crimea in SuukSu there's a crag named Pushkin. I decided to build there a Castle of Arts. I told myself: kings and knights had castles. Why wouldn't artists had a castle? F. I. Chaliapin."

Nikita


We visited Nikitskiy Botanical Garden. It's small (couple hours is enough to walk it) but very very nice.


Chatyr-Dag


We visited amazing Emine-Bair-Khosar and Marble caves in Chatyr-Dag mountain.


Alupka


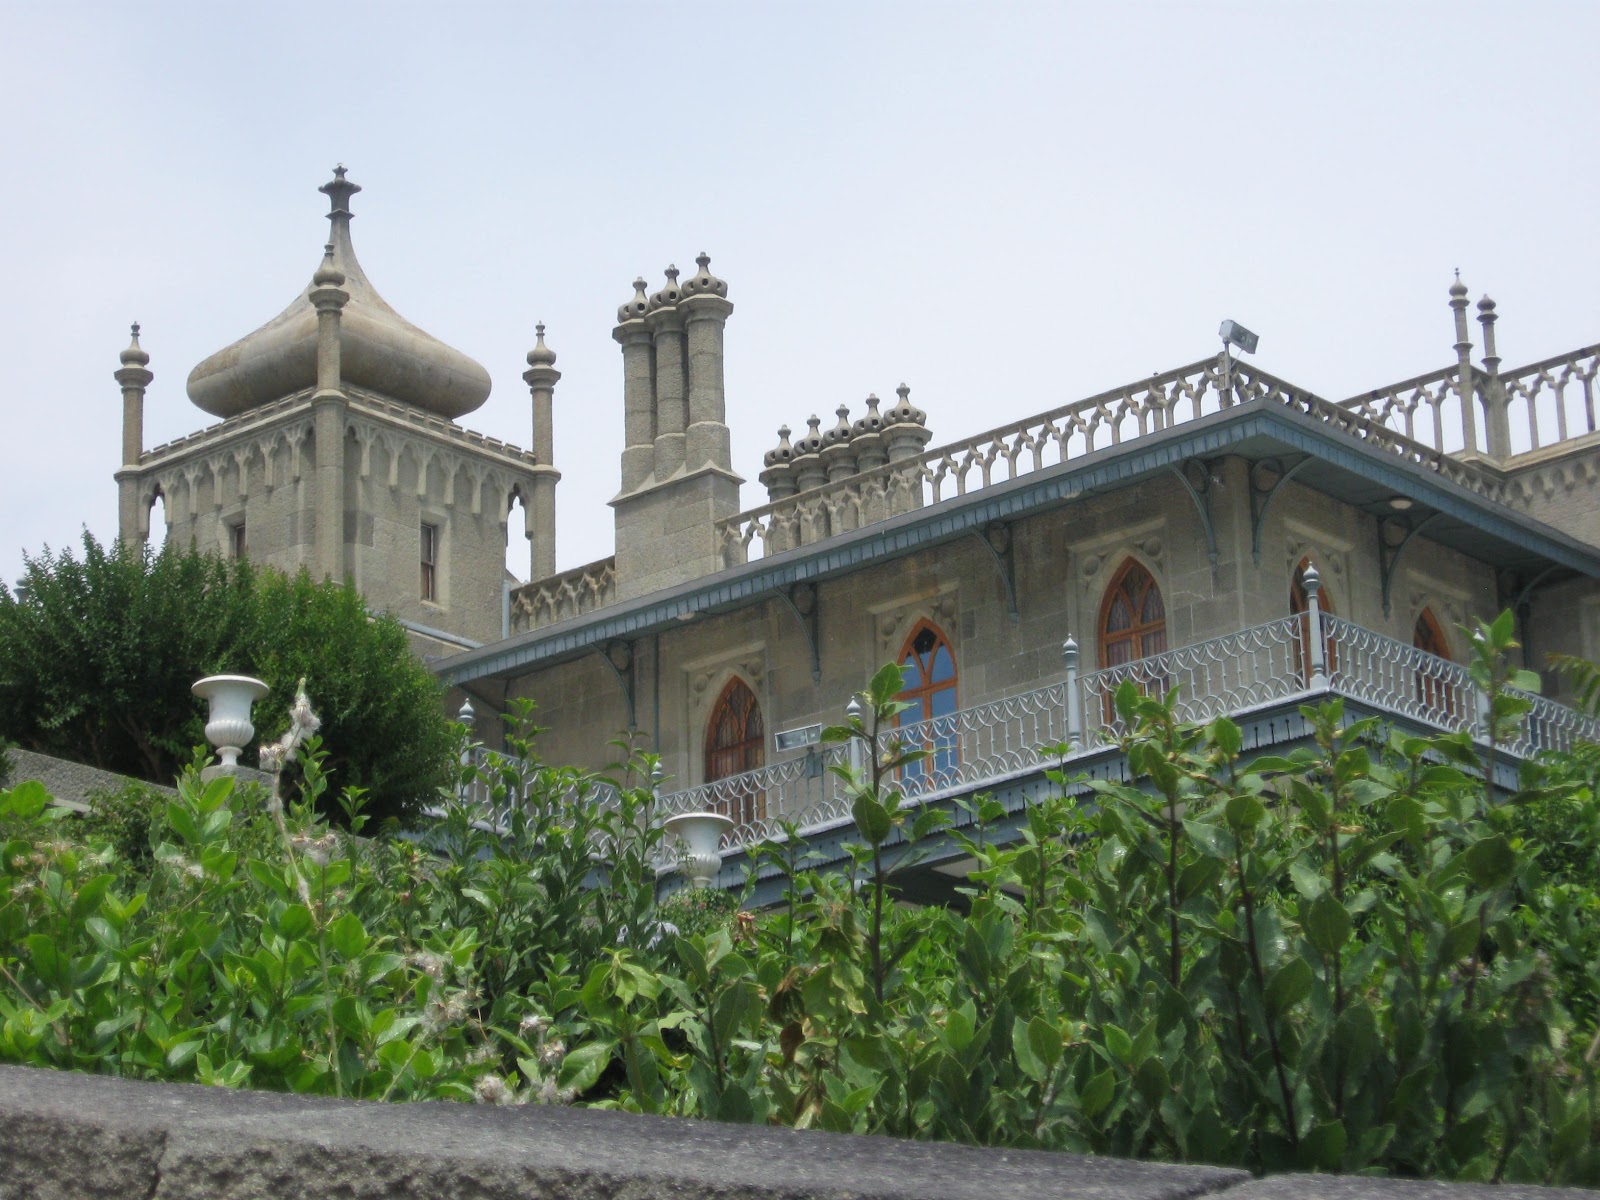
Then we moved to Alupka. Alupka is Vorontsov Palace and Vorontsov Park. Park is nice, palace is majestic. Rest of Alpuka didn't make any impression.


Big Yalta


Around Yalta (referred as Big Yalta) there are a lot of attractions including Vorontsov Palace in Alupka I mentioned above. We visited some of them.

Ai-Petri is a mountain and there's Gondola lift there. A flat plateau on the top, couple caves, a lot of restaurants of eastern cuisine and amazing view.


The Swallow Nest in Gaspra, a tiny palace over the cliff. Nowdays it's museum.


Yusupov palace is resort of Ukraine government nowdays but it's open for tourists occasionally.


The Livadia Palace of Nicolas II, Russian tsar.


The Massandra Palace, a country house of Alexander III, Russian tsar.


Sevastopol


Then we moved to Sevastopol. Sevastopol is hero city, participant of two wars: Crimean War and World War II. It has large amount of monuments and very handsome.


The Panorama Museum (The Heroic Defence of Sevastopol during the Crimean War).


The Monument to the Scuttled Ships. 


There's ancient Greek city named Chersonesos.


Frunze


Then we moved to Frunze, village near of the Saki city, a medicinal resort. Frunze is the sea and pebble beach, nothing else. Pretty quite. 

Few hours we spent walking in Saki. It's ashore the Saki lake known because of its medical mud. There's lot of people using wheelchairs there.


Yevpatoriya


And finally we moved to Yevpatoriya. It has long sand beaches and nice downtown. A good place for children.


Tarkhankut


Tarkhankut is one of beautiful place of Crimea: cliffs, caves, tunnels and diving of course.


Getting back


Rossiya Airlines surprised us one more time when were heading up home. They moved our initial flight from Simferopol right after our connection flight from Saint-Petersburg. So we spend couple days in Saint-Petersburg waiting for the next flight. The good thing they paid for the hotel and food.

We visited Petergof Palace and Leningradskiy Zoopark next day.


So if you wanna take a look at Saint-Petersburg then please choose Rossiya Airlines. It's really amazing city.